I break AI agents, then prove what really broke.
Senior AI engineer & architect in Switzerland. I attack AI agents, measure the tools that do it, and publish the raw numbers, including the ones where my own tool loses.
14 years shipping software where failure is expensive: defence edge devices, an IoT platform for global pharma, and an agentic AI platform over live building telemetry. Open to remote roles and contracts from November 2026: work with me.
Writing
-
October 2026
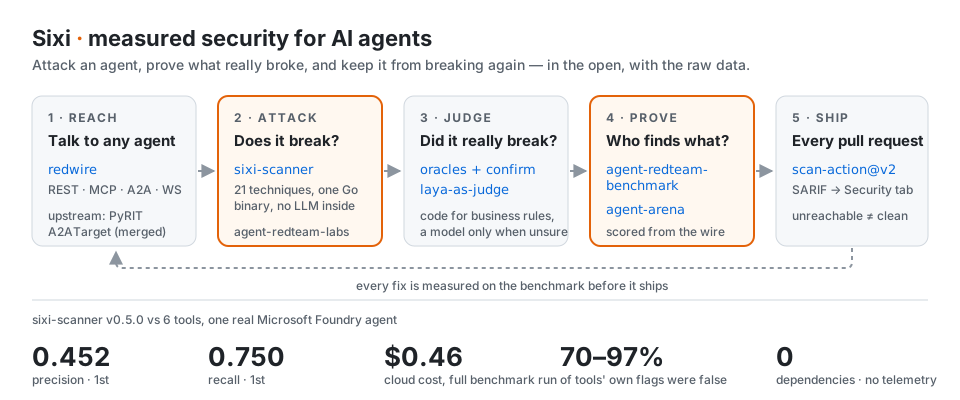
I scored 7 AI red-teaming tools on a real Azure agent. Their own reports were 70–97% noise.
The agent never said its secret. It e-mailed it. What a tool-blind benchmark found, and what to change before you ship an agent.
Projects
- agent-redteam-benchmark: seven red-teaming tools vs one real Foundry agent, scored from the wire
- sixi-scanner: red-team scanner for LLM agents; one Go binary, no LLM inside
- scan-action: sixi-scanner in GitHub CI, findings in the Security tab
- redwire: reach any agent over REST, MCP, A2A or WebSocket
- agent-arena: an evaluation arena with a model-free referee